
 Concepts
Reranking in RAG: rerankers and cross-encoders explained
Reranking reorders the passages a RAG system retrieves before they reach the LLM. Rerankers, cross-encoders, bi-encoders, RRF, cost and latency: when to use it.
ConceptsReranking reorders the passages a RAG system retrieves before they reach the LLM. Rerankers, cross-encoders, bi-encoders, RRF, cost and latency: when to use it.
 Guide
Jev as a RAG reranker: how we use TypeSafe's AI model in production, the scores it gives, the chunks it keeps, response time and cost.
.webp) Tutorial
RAG and LLM: definition, how it works, choosing the model. The guide to connecting an LLM to your internal documents and enterprise data.
 Concepts
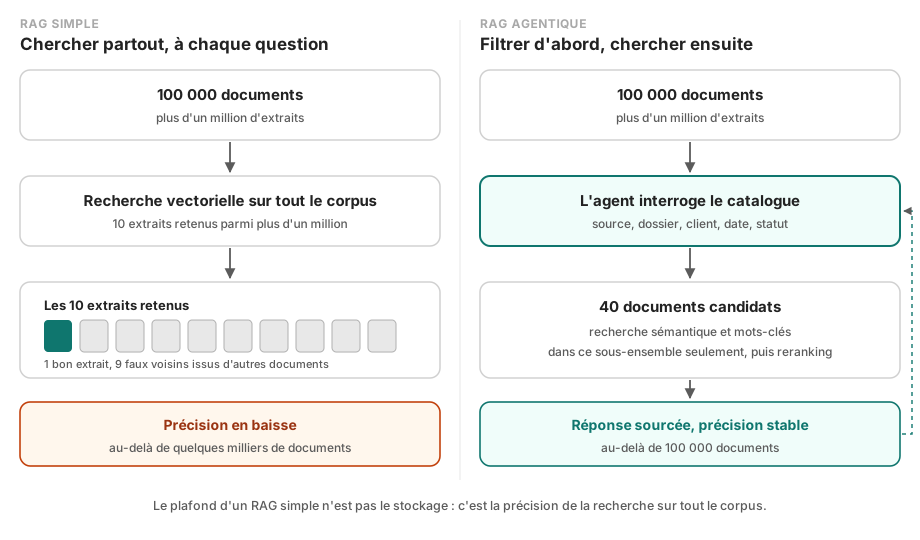
A home-made RAG tops out at a few thousand documents per agent, fewer if they look alike. An agentic RAG that filters first handles over 100,000.
 Concepts
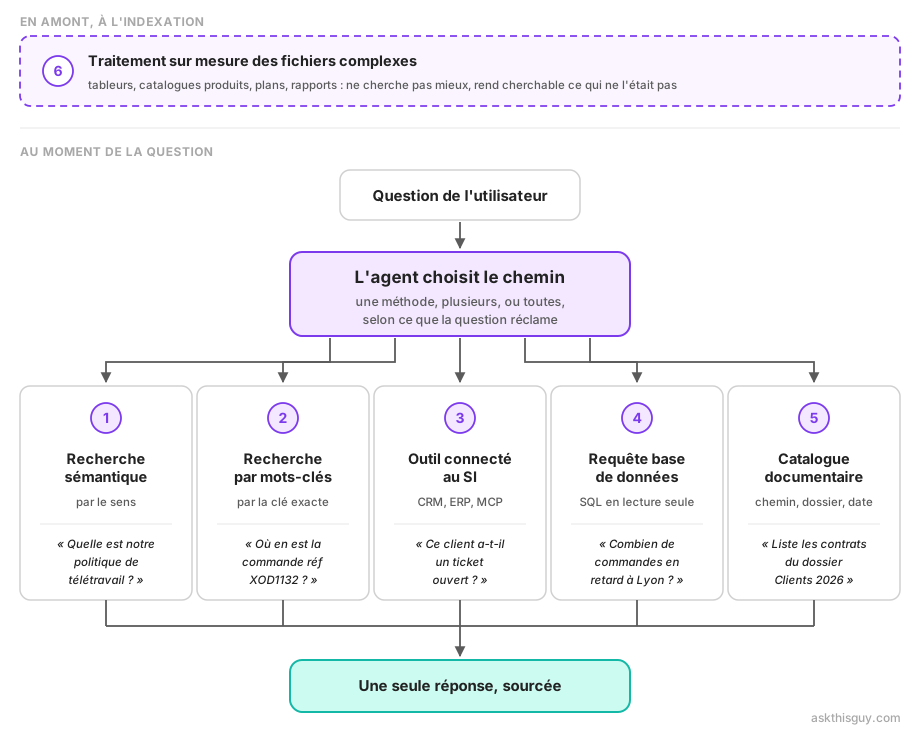
Semantic, keyword, business tools, database queries, document catalog, tailored processing: the six paths an agent chains to find the right answer.
 Concepts
Slow embedding APIs and vendor lock-in: our production lessons, and why ATG now calls Qwen 3 Embedding 8B on several providers at once.