
 Concepts
Reranking in RAG: rerankers and cross-encoders explained
Reranking reorders the passages a RAG system retrieves before they reach the LLM. Rerankers, cross-encoders, bi-encoders, RRF, cost and latency: when to use it.
ConceptsReranking reorders the passages a RAG system retrieves before they reach the LLM. Rerankers, cross-encoders, bi-encoders, RRF, cost and latency: when to use it.
 Guide
Your in-house RAG disappoints? A 7-layer audit grid, tests to run on your own tool, an evaluation method and criteria to decide whether to fix or replace it.
 Concepts
FDE meaning: a forward deployed engineer is a software engineer who works at the customer. Origins at Palantir, role, skills, salaries, versus consulting roles.
 Guide
Using your own AI on a Datasite, Intralinks or iDeals data room: built-in assistant, MCP or file access. What each room actually allows, and where it stops.
 Concepts
 Guide
Jev as a RAG reranker: how we use TypeSafe's AI model in production, the scores it gives, the chunks it keeps, response time and cost.
 AI
On-premise LLM in 2026: GPU prices, memory per model, full TCO and break-even against the same model via API. Figures to decide between Make and Buy.
 Guide
Why one provider is not enough for an enterprise AI SLA. Compare commitments, multi-provider gateways and fallbacks for RAG and AI assistants.
.webp) Tutorial
RAG and LLM: definition, how it works, choosing the model. The guide to connecting an LLM to your internal documents and enterprise data.
 Concepts
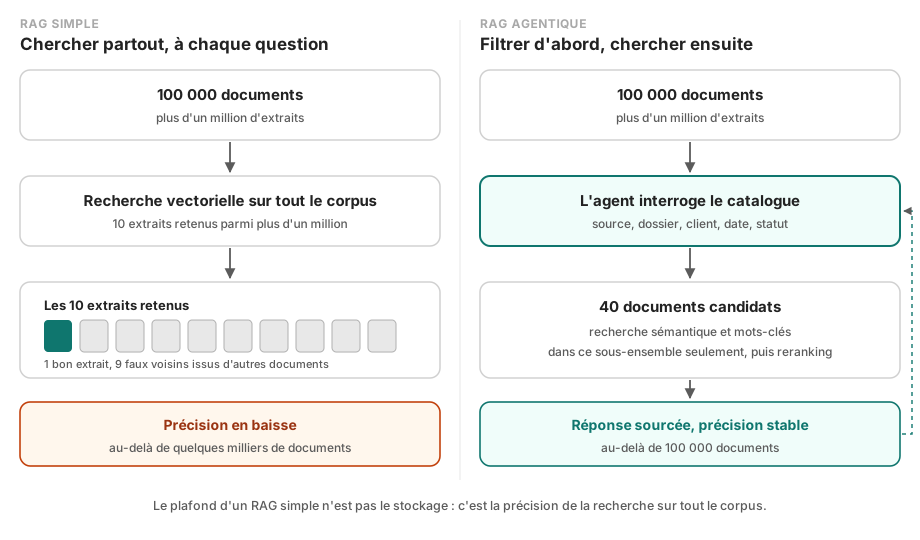
A home-made RAG tops out at a few thousand documents per agent, fewer if they look alike. An agentic RAG that filters first handles over 100,000.
 Guide
Mistral OCR costs $4 per 1,000 pages. An open-weight OCR on a European GPU drops to $0.15 and stays sovereign. Benchmark, break-even point and pitfalls.
 Guide
Neural networks, tokens, training, fine-tuning, hallucination, LLMOps: the ten concepts that explain where your AI budget goes and where your dependency begins.
 Concepts
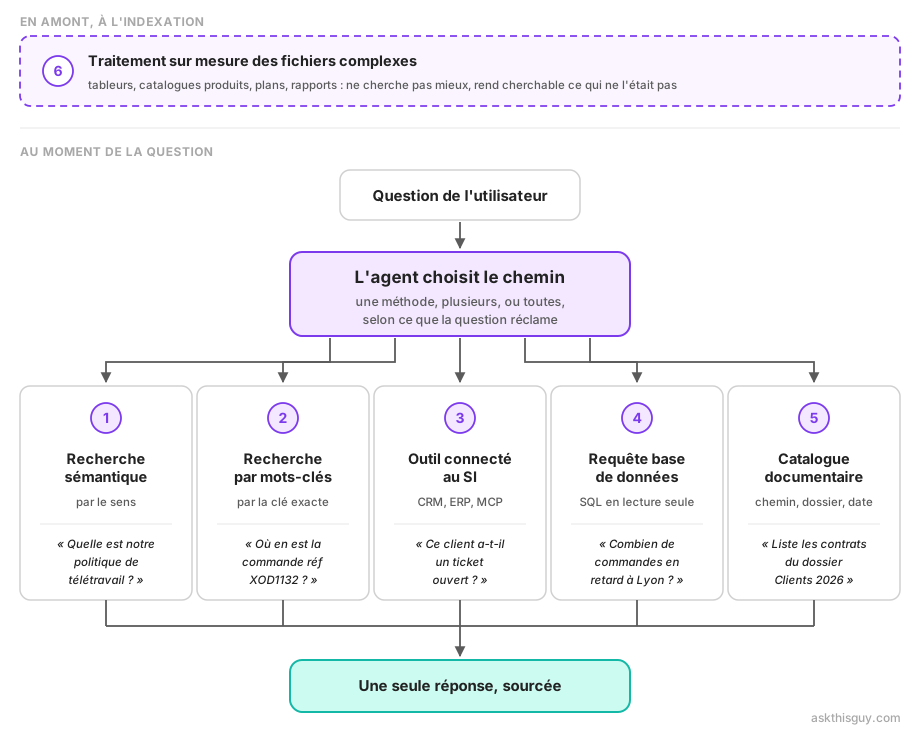
Semantic, keyword, business tools, database queries, document catalog, tailored processing: the six paths an agent chains to find the right answer.
 Guide
Why knowledge management initiatives fail, what AI really changes about managing what a company knows, and what it will never change.
 Guide
Internal company chatbot: what it is really for, how it differs from a website chatbot, the classic pitfalls and the conditions for success.
 Guide
Discover 6 concrete productivity gains that contextual AI with RAG can bring to a company by structuring and sharing its knowledge more effectively.
 Guide
An enterprise RAG is relatively easy to prototype. Making it a useful, stable product is a much bigger challenge. Here are the five most common production pitfalls—and how to get ahead of them.
 Product
Juggling enterprise systems, getting a simple answer often takes twenty minutes (or a Teams ping to the “person who knows”). Your real data lives in structured databases: it’s often reliable, up to date… but also inaccessible. Most companies seem to overlook it, yet AI can query it in plain language and cross-reference documents and databases in seconds.
 Demo3:41
Deploy an enterprise chatbot in 3 minutes.
 Concepts
Slow embedding APIs and vendor lock-in: our production lessons, and why ATG now calls Qwen 3 Embedding 8B on several providers at once.