
 AI
Qwen 4 27B vs Qwen 3.8 27B: What to Expect from Qwen 4
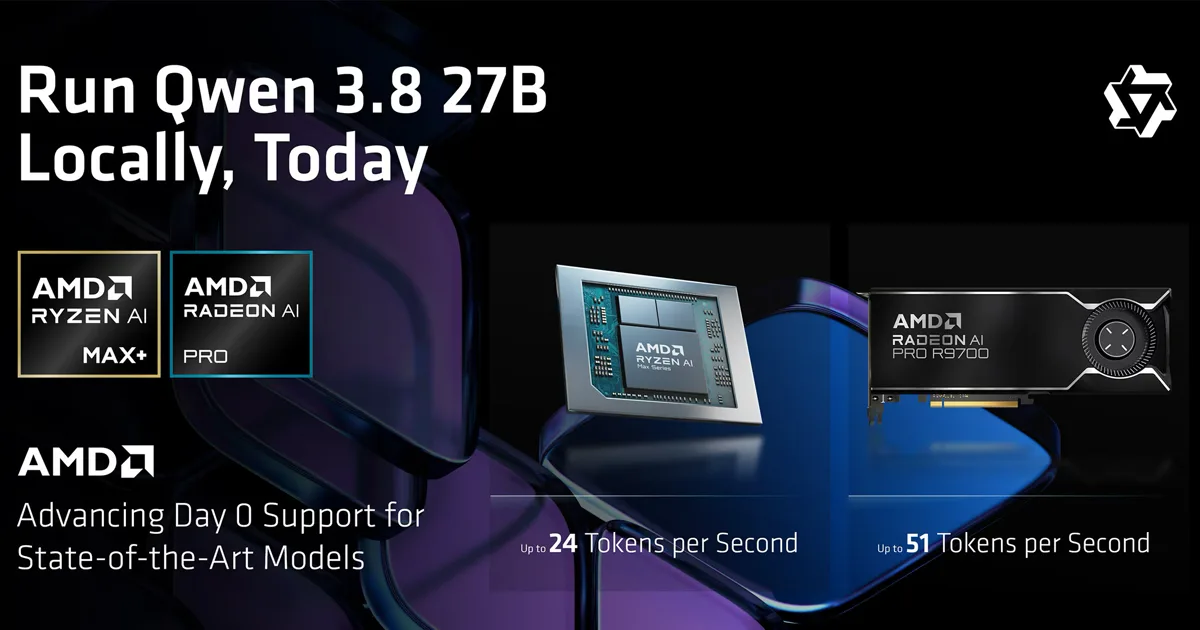
This article reviews what is confirmed about Qwen 4 27B, Qwen's upcoming model, and how Qwen 3.8 27B, a dense model on one GPU, compares with Mistral models.
AIThis article reviews what is confirmed about Qwen 4 27B, Qwen's upcoming model, and how Qwen 3.8 27B, a dense model on one GPU, compares with Mistral models.
 Concepts
Mixture of experts (MoE) vs dense LLMs: how each architecture works, what it changes for your GPUs, speed and price per token, and which one to choose.
 Digital Sovereignty
OVHcloud is announcing its own LLM and wants the whole AI stack. What already exists (GPUs, AI Endpoints), what is still unproven, what IT leaders can learn.
 Digital Sovereignty
For all its products, Mistral AI declares just two compute operators: its own servers and CoreWeave, whose debt is in distress. What a default would change.
 Guide
LLM gateway or AI gateway: what it does, OpenRouter vs LiteLLM, what it costs and where your data goes. Our own price and speed readings included.
 Guide
Enterprise AI inference: 7 approaches compared, from buying GPUs to a turnkey provider. Real costs, sovereignty, latency and how to choose.
 Guide
Why one provider is not enough for an enterprise AI SLA. Compare commitments, multi-provider gateways and fallbacks for RAG and AI assistants.
 AI
On-premise LLM in 2026: GPU prices, memory per model, full TCO and break-even against the same model via API. Figures to decide between Make and Buy.