
 AI
LLM translation: OVHcloud's Olala tested against DeepL
LLM translation tested: OVHcloud's Olala Translate against DeepL and gpt-oss-120b on 100 business document chunks. Fidelity, fluency, cost and speed compared.
10 min
AILLM translation tested: OVHcloud's Olala Translate against DeepL and gpt-oss-120b on 100 business document chunks. Fidelity, fluency, cost and speed compared.
 AI
Qwen4-Max shipped on November 16 without weights; Qwen 4 27B is still not out. What is confirmed, and how Qwen 3.8 27B compares with Mistral models.
 AI
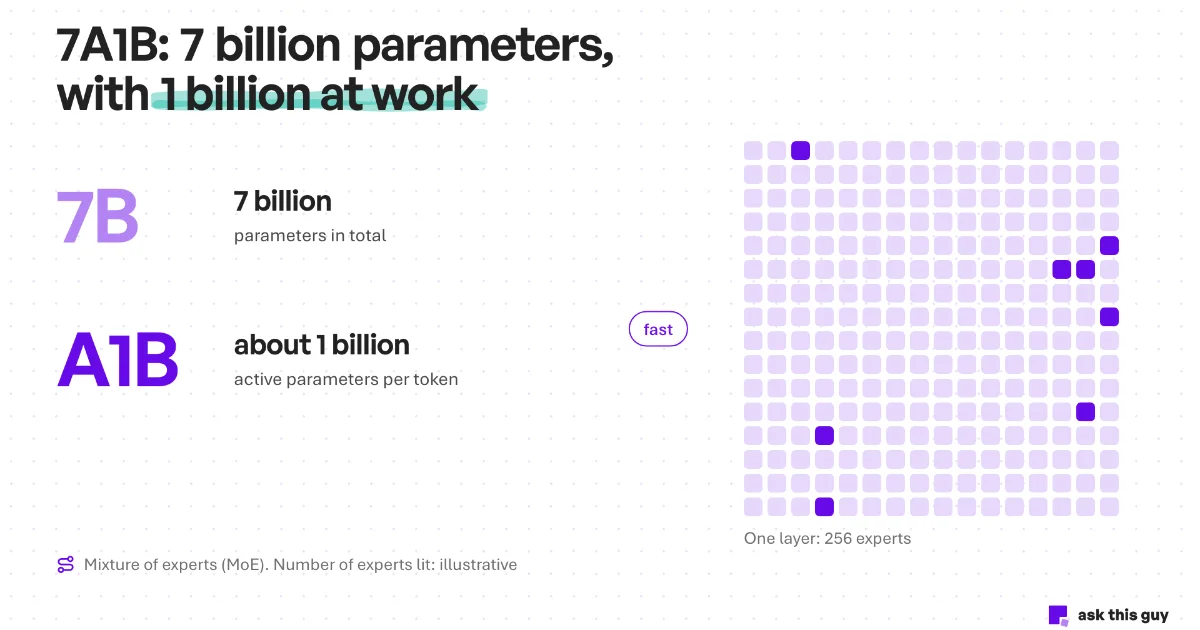
Olala mini 7A1B, OVH's first LLM, is now on Hugging Face. Its scores against Qwen and Ministral, how to run it locally, what it can do for businesses.
 AI
Local LLM server: workstation, RTX PRO 6000 card or H200. What each tier serves with Qwen 3.8 27B, measured throughput and prices checked in November 2026.
 Concepts
Open-source AI in the enterprise: what each open model license really allows, how much it saves compared with closed APIs, and why the rules are tightening.
 AI
DeepSeek V4.1 Pro is not out as of November 16. What is confirmed, what the leaks are worth, and DeepSeek V4 Pro today: pricing, MIT license, data location.
 Guide
LLM gateway or AI gateway: what it does, OpenRouter vs LiteLLM, what it costs and where your data goes. Our own price and speed readings included.
 Concepts
Open-weight or open-source model: definition, differences, licences and enterprise use. Why an LLM is almost never open-source the way Linux is.
 Concepts
We asked seven AI models for a number between 1 and 10, 14,000 times. Five answer 7 almost every time, whatever the temperature. Where does this bias come from?
 Concepts
Mixture of experts (MoE) vs dense LLMs: how each architecture works, what it changes for your GPUs, speed and price per token, and which one to choose.
 Concepts
Can an AI replicate itself? What Anthropic tested on connected devices, AI worm versus AI virus, the study's limits and what businesses can do about it today.
 Concepts
OpenAI and Anthropic accuse Chinese labs of distilling their models. Yet Meta, Google, Mistral and even Musk's xAI distill too. Here is what we actually know.
 Guide
Enterprise AI inference: 7 approaches compared, from buying GPUs to a turnkey provider. Real costs, sovereignty, latency and how to choose.
 Guide
Why one provider is not enough for an enterprise AI SLA. Compare commitments, multi-provider gateways and fallbacks for RAG and AI assistants.
 Guide
Mistral OCR costs $4 per 1,000 pages. An open-weight OCR on a European GPU drops to $0.15 and stays sovereign. Benchmark, break-even point and pitfalls.
 Concepts
Slow embedding APIs and vendor lock-in: our production lessons, and why ATG now calls Qwen 3 Embedding 8B on several providers at once.